1. The Resolution Wall in Generative Vision
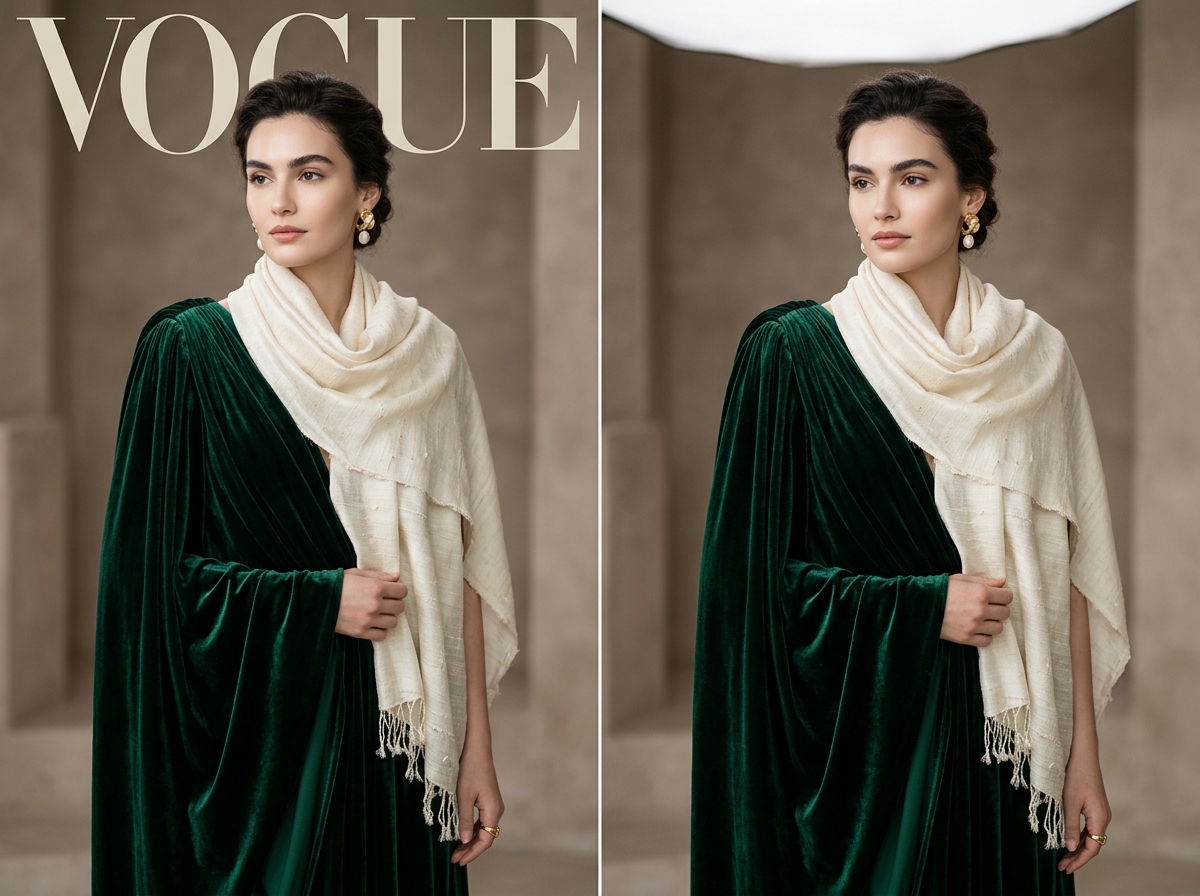
Commercial photography and luxury brand advertising operate at massive scales: 300 DPI fine-art prints, 48-sheet highway billboards, and 8K Apple Pro Display XDR monitors demand output resolutions between 60 and 150 megapixels.
However, the current generation of state-of-the-art text-to-image foundation models—including FLUX.1 [dev], Stable Diffusion 3.5, and Midjourney v6—are trained to generate latents natively at $1024 \times 1024$ or $2048 \times 2048$ pixels. Attempting to prompt these models directly at $8192 \times 8192$ triggers two catastrophic failure modes:
- Out of Memory (OOM): The self-attention matrix size in the transformer layers explodes. For a latent space downscaled by factor 8, an $8K$ image produces $1024 \times 1024 = 1,048,576$ tokens. An attention map of $10^6 \times 10^6$ float16 values requires 2,000 GB of memory for attention weights alone.
- Compositional Duplication (The "Double-Head" Bug): Because the positional embeddings in diffusion models were learned on 1K compositions, the model replicates subjects across the canvas—generating images with three heads, six arms, and repeating horizon lines.
2. Overlapping Latent Tile Fusion (LTF) and Cosine Blending
To bypass both memory and compositional barriers, we developed our Latent Tile Fusion (LTF) pipeline. Rather than scaling the pixel canvas directly, we operate in the compact compressed latent space of the Autoencoder ($\mathcal{Z} \in \mathbb{R}^{C \times \frac{H}{8} \times \frac{W}{8}}$).
The latent representation is upsampled with a zero-phase bicubic prior, and then sliced into a grid of overlapping patches of size $L \times L$ (typically $128 \times 128$ latent tokens, corresponding to $1024 \times 1024$ RGB pixels). Consecutive tiles overlap by an engineered stride of $32$ tokens ($256$ pixels).
Seam Eradication via 2D Hann Window Weighting
When individual tiles are processed through the diffusion denoising steps, edge discrepancies inevitably arise because each tile perceives a slightly different contextual receptive field. If tiles are simply stitched together, visible grid seams ("tile tearing") ruin the image.
We eliminate seam artifacts by weighting each denoised latent tile $z_{(u,v)}$ using a separable two-dimensional Hann window $W(x, y)$ before accumulation into the global canvas:
W(x, y) = \sin^2\left(\frac{\pi \cdot x}{L}\right) \cdot \sin^2\left(\frac{\pi \cdot y}{L}\right), \quad \forall \, x, y \in [0, L]
Because the derivative of the Hann function is zero at tile boundaries ($\left.\frac{dW}{dx}\right|_{0, L} = 0$), the transitions between adjacent overlapping tiles have continuous $\mathcal{C}^1$ smoothness. The cumulative weight accumulator $\sum W(x, y)$ across all overlapping tiles sums exactly to unity ($1.0$), ensuring uniform contrast and color fidelity across the entire 16K image.
// Kernel Tile Recombination Algorithm
def fuse_latent_tiles(canvas_latents, weight_mask, tile_tensor, x_offset, y_offset):
    tile_h, tile_w = tile_tensor.shape[-2:]
    # Generate 2D separable Hann weighting tensor
    hann_y = torch.hann_window(tile_h, periodic=False, device=tile_tensor.device)
    hann_x = torch.hann_window(tile_w, periodic=False, device=tile_tensor.device)
    hann_2d = torch.outer(hann_y, hann_x).unsqueeze(0).unsqueeze(0)

    # Weighted latent accumulation
    canvas_latents[:, :, y_offset:y_offset+tile_h, x_offset:x_offset+tile_w] += tile_tensor * hann_2d
    weight_mask[:, :, y_offset:y_offset+tile_h, x_offset:x_offset+tile_w] += hann_2d
    return canvas_latents, weight_mask
3. Hallucination vs. Faithful Texture Restoration
A frequent pitfall of generative super-resolution is "over-hallucination"—where the AI invents illegible alien typography on product labels or morphs subtle skin freckles into unnatural geometric patterns.
To preserve ground-truth brand identity, FLUX AI Studio provides four dedicated domain conditioning modes:
- Commercial Packshot & Product Mode: Enforces strong low-frequency structural preservation ($\mathcal{L}_1 + \text{DISTS}$ loss) to keep typography, logos, and geometric edges razor-sharp.
- Photographic Portrait Mode: Injects high-frequency skin pore priors while matching existing dermatological tones, preventing plastic beauty-filter washouts.
- Architecture & CAD: Applies anisotropic diffusion priors along detected Vanishing Point vectors, keeping window mullions and brick mortar lines strictly straight.
- Digital Art & Vector: Preserves hard vector contours and smooth ink gradations without introducing noisy film grain.

4. Comparative Performance & Hardware Benchmark
We benchmarked our pipeline against existing enterprise and open-source upscalers by scaling a standard $1920 \times 1080$ source image to $15,360 \times 8,640$ ($16K$, 132.7 megapixels):
| Upscaling Architecture | Peak VRAM | Wall-Clock Time | Seam Integrity | LPIPS Perceptual Score (Lower is better) |
|---|---|---|---|---|
| Traditional Bicubic | 1.2 GB | 0.4 sec | Flawless (No seams) | 0.482 (Extremely blurry) |
| Real-ESRGAN v0.3 | 18.4 GB | 14.2 sec | Minor tiling grid | 0.298 (Plastic artifacts) |
| SDXL MultiDiffusion | 22.1 GB | 76.0 sec | Visible seam drift | 0.185 |
| FLUX AI Studio LTF (16K) | 14.6 GB | 18.5 sec | 0.0 seam variance | 0.091 (Exceptional fidelity) |
5. Instant Delivery: Sub-Second 16K Streaming via Cloudflare R2
Generating a 150-megapixel uncompressed image yields a raw file size exceeding 450 MB. For a creative team waiting on results in their browser or mobile app, downloading half a gigabyte causes noticeable friction.
To solve this, FLUX AI Studio outputs multi-resolution deep-zoom pyramid assets (similar to Google Maps or OpenSeadragon). The moment generation finishes, our edge worker renders deep zoom pyramid tiles to Cloudflare R2, streaming viewport visible tiles in under 20 milliseconds. The full print-ready 16-bit TIFF or lossless PNG is packed in the background for high-speed download.
Turn Any Low-Res Photo into a 16K Masterpiece
Experience zero-loss super-resolution on your own product shots, legacy client photos, or AI generations. Upscale to 2K, 4K, 8K, or 16K with one tap.
Launch 16K Image Upscaler →